Your cloud providers are good at what they do. On AWS, Glue transforms data, Step Functions coordinates serverless workflows and EventBridge routes events. Azure and Google Cloud have their own equivalents, and each one reliably handles the steps inside its own boundary.
The problem is that your most important business processes rarely stay inside one boundary. A month-end report might start with an extract from an on-premises database, pass through several AWS services and finish in a data warehouse that Finance reviews at 8 AM. An invoice might arrive from a supplier, get matched in AWS and need to be posted to SAP before the payment run.
Every service in either chain can report success while the business process still fails. A green Glue job doesn’t prove the source data was complete. A completed Step Functions workflow doesn’t prove SAP received the result. Each service sees its own part of the process, but someone still has to own the whole thing.
1. The hybrid data pipeline that starts outside AWS
Picture a common pipeline. Every night, a legacy on-premises system (an Oracle E-Business Suite instance, a plant-floor database or a warehouse management system) exports data. The file lands in Amazon S3, AWS Glue transforms and catalogs it and the results load into Snowflake, where an analytics dashboard refreshes before the business day starts.
Inside AWS, S3 stores the data reliably and Glue handles the transformation at scale. Neither can tell you whether the on-premises extract finished late, arrived partially or never arrived at all.
These failures tend to fly under the radar. A late extract can leave Glue processing yesterday’s data without complaint. A partial file can produce a dashboard that looks plausible but is wrong. And the hardest case is a step that never triggers at all, because there’s no error — just an absence. Someone notices when a report looks stale, often hours or days later, and the investigation starts with a simple question: where did the process break?
Bringing the full chain under RunMyJobs adds the context the individual services don’t have:
Dependency-based sequencing: The S3 landing, Glue job and Snowflake load wait for the on-premises extract to complete and pass the checks you define.
One view of the chain: Operators can see status and projected completion without moving between consoles and teams.
An SLA on the business outcome: RunMyJobs can track whether the dashboard will be ready by 8 AM and warn the team before that deadline is at risk.
Faster failure identification: When something goes wrong, you know which step failed, or which one never started, without piecing it together across teams and tools.
Less custom code, less wasted compute: Pipelines run when the data is ready, not on a fixed polling schedule that burns compute checking for files that haven’t arrived.
RunMyJobs doesn’t replace Glue or S3. It governs the process they belong to, including the part that starts outside AWS.
2. The SAP invoice that needs AWS to finish its job
AWS publishes reference patterns to show how its services fit together, and many real projects start from one. A good example uses Amazon AppFlow, Amazon Textract and AWS Step Functions to automate invoice matching against SAP S/4HANA data. It’s a useful picture of the processing inside AWS.
Production architecture also has to account for what surrounds that processing. What starts the workflow? How does it know the SAP data is current? What posts the result? Will the work finish before the next payment run?
Those questions are often answered with custom triggers, scripts and point-to-point integrations that never appear on the reference diagram. That hidden coordinsssation creates the risk of matching against stale SAP data, missing a handoff back to SAP or allowing a payment run to proceed after an overnight failure. It also creates code that has to be retested when SAP or an AWS service changes.
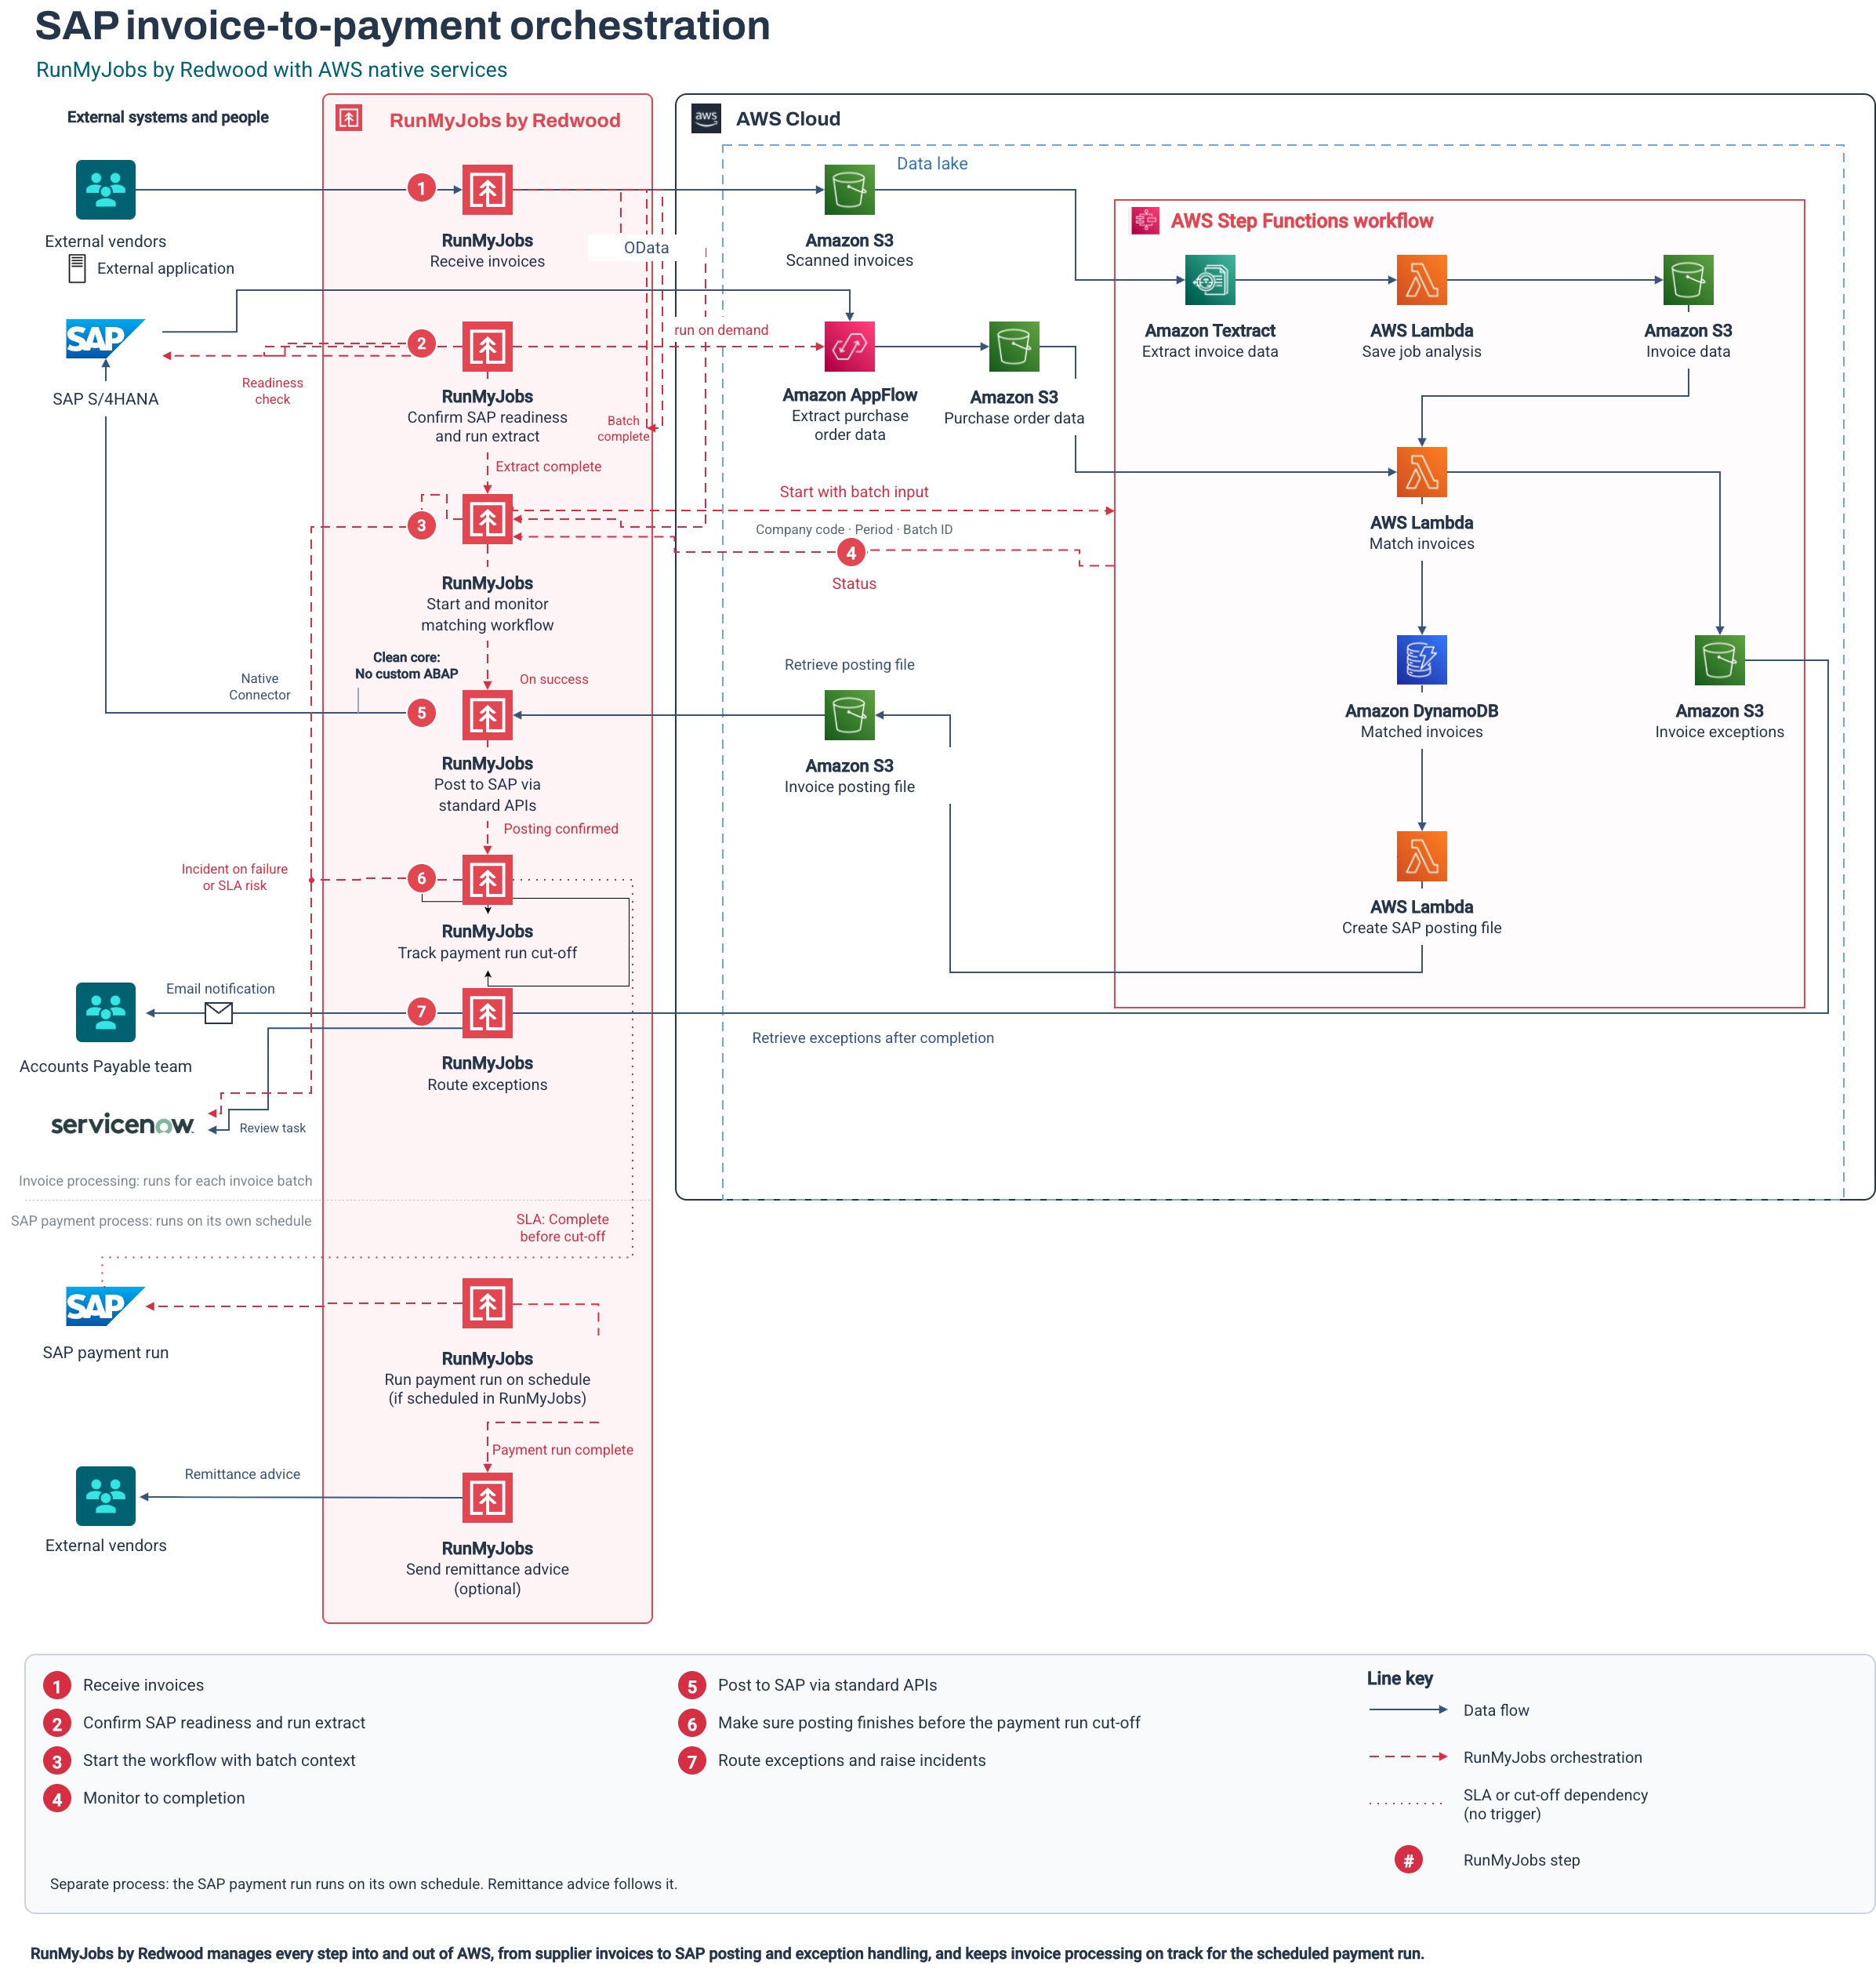
The architecture below adapts the AWS pattern from sales orders to a common accounts payable scenario based on purchase orders and goods receipts. The AWS example matches invoices against sales orders. Here, we use the version most accounts payable teams know as a three-way match, where the invoice, purchase order and goods receipt all have to agree.
The AWS Step Functions connector lets existing Standard state machines be imported as reusable RunMyJobs job definitions and run alongside SAP jobs. The AWS workflow keeps the branching, retries and parallel processing it was built for. RunMyJobs adds the cross-system dependency graph, SLA and operational history around it. Step Functions still owns the matching workflow. RunMyJobs coordinates the work around it as part of the full procure-to-pay process:
RunMyJobs picks up supplier invoices as they arrive, lands them in Amazon S3 and confirms the batch is complete
It checks that SAP has finished posting the latest purchase orders and goods receipts, then copies that data into Amazon S3 so the workflow can compare it with the invoices
It starts the state machine with business context such as company code, period and batch
It monitors the execution until it succeeds, fails or times out and can stop it if an upstream problem makes the result unsafe to use
When matching succeeds, it posts the result to SAP S/4HANA through the appropriate standard API using the native SAP connector (with no custom ABAP code)
It tracks completion against the scheduled payment run’s cut-off and warns the team if the process is at risk of missing it
It routes invoice exceptions to Accounts Payable and can open a ServiceNow incident when the process threatens the SLA
Architecture adapted from the aws for sap blog referenced above. Click to enlarge.
The payment run is usually a separate process on its own schedule, so the architecture treats its cut-off as a deadline rather than the next step. If RunMyJobs also schedules the payment run, some finance teams may choose to hold it when invoice processing fails. That adds control at a critical close and delays correctly posted invoices until the run is released.
This also supports a cleaner SAP core. Pre-built SAP connectors and standard interfaces reduce the custom ABAP and tightly coupled integrations that otherwise accumulate around cross-system processes. RunMyJobs is the only workload automation and orchestration platform that is an SAP Endorsed App and part of the RISE with SAP reference architecture.
3. The reconciliation break that needs judgment, not a queue
The third opportunity starts with a process you may already run in RunMyJobs.
Take reconciliation. The job compares the general ledger with a bank feed or sub-ledger, and it runs reliably at scale: one customer’s reconciliation job runs about 52,000 times a year. When a comparison fails, however, the result may be little more than a red status. Then someone has to pull data from every system involved, find where the values diverged, determine the cause and decide whether to fix the break or escalate it. In a complex reconciliation, that investigation can span as many as nine systems.
That’s skilled detective work, but much of it is evidence gathering. It also gets harder as the process becomes more reliable. Breaks become rarer, so fewer people remember what the usual issue looks like, and each investigation starts cold.
Agent Studio in RunMyJobs lets you build a governed agent and add it to the reconciliation job chain you already have. When a break occurs, the agent:
Checks the same upstream systems an analyst would
Proposes the most likely cause
Resolves a recurring pattern it’s authorized to handle
Escalates a new or consequential case, with the investigation already attached
Imagine a break shows up at 6 AM on the last day of the month. The bank feed and general ledger differ by a few cents across dozens of lines. Without help, that’s the first hour of an analyst’s day. Instead of asking an analyst to begin with only the fact of failure, the agent can trace the difference to an FX rounding pattern, collect the supporting evidence and either apply an approved resolution or send the worked-up case to a person.
The deterministic reconciliation process still handles every transaction. The agent only acts when a case needs judgment, concentrating AI use on the exception path rather than the full transaction volume. Because the agent runs as a workflow step, it inherits the workflow’s
governance and observability. You define its skills and tools, set timeout and cost controls and decide which patterns it may resolve or must escalate. The audit trail shows what the agent did in the context of the process that called it.
Coming next for the AWS Step Functions connector
The next planned update to the connector would bring:
Execution results returned to RunMyJobs: Downstream steps could use a completed state machine’s output directly without a separate storage handoff.
Express workflow support: RunMyJobs could start Express state machines synchronously or asynchronously.
Express discovery and import: Teams could list Express state machines and bulk-import them as RunMyJobs job definitions, as they can with Standard workflows today.
Where to extend RunMyJobs next
Not every AWS activity needs RunMyJobs in front of it. Start with a business-critical process that crosses a boundary: an on-premises extract feeding AWS, an SAP process waiting on a state machine or an automated job that still hands every exception to a person.
Then ask who owns visibility across the whole thing. If the answer is “nobody,” that’s where to extend RunMyJobs next.
Schedule an AWS orchestration reviewwith a Redwood Software expert to identify where RunMyJobs can add visibility and control across your hybrid cloud workloads.
For the past decade, cloud was the “new frontier.” It redrew the map of enterprise IT, opening new territory for applications, data and business services. Organizations could build faster, support more use cases and deploy technology into more areas of the business. That delivered enormous value, but with it created unmitigated sprawl: the number of systems where business-critical work happens has expanded.
Over time, the complexity spiraled out of control. Cloud services, SaaS applications, data platforms and systems of record became interconnected parts of the same business processes. Highly connected enterprise applications calling cloud services that start data pipelines, update SAP and then open ServiceNow tickets is the new norm. Paths like this are the result of years of useful IT investment.
AI is the next wave moving across that landscape, and executives are challenging every business function to use it to scale operations and increase capacity. Many are building agents to solve business problems: everything from managing calendars and email to investigating production errors and resolving process exceptions. In a 2026 Deloitte survey, 74% of leaders at organizations already piloting agentic AI expected nearly half of their business processes to be redesigned or rebuilt around AI agents within four years. As the industry wrestles with the transition from AI agents doing low-risk, read-only tasks to taking action in highly sensitive production environments, we’re watching a new class of workload emerge in an already complex hybrid IT operating model.
How do we manage the risks and value of this new type of workload? IT Ops has an opportunity to establish a consistent way for agents to act across the enterprise. Hybrid cloud orchestration builds on each environment’s native controls, keeping workflow policies, safety mechanisms and business context attached to an agent-initiated action as it moves across the hybrid estate. Each agent may have only a part of the overall context, and the intelligence ends at the border of its reach within a system. Productive autonomy depends on agents being capable of exploring new possibilities while acting through execution paths the enterprise can trust, across many different systems.
Commoditized agents make governed execution more valuable
Managed models, cloud AI services, copilots, low-code builders and agent frameworks have dramatically compressed agent development time. A team can now turn an idea into a polished demonstration before asking IT Ops how the agent will authenticate, which systems it can change or who will own the outcome. As more teams build agents, the cost of supporting each new use case will depend on how much execution logic, policy and recovery handling they can reuse.
When an agent moves from investigating a production error to restarting a service, rerunning a pipeline or rolling back a deployment, it crosses from reasoning into production execution. That creates a familiar challenge for IT Ops: give the agent enough authority to resolve the issue quickly, with safeguards that prevent an accidental database deletion from becoming front-page news. The operational disciplines are established, and we’re just changing the actor from an IT Ops engineer to an AI agent.
The boundary is between reasoning and execution:
The agent interprets context, evaluates options and selects or proposes an action
The execution layer applies policy and guardrails, validates dependencies, invokes the approved workflow and records the outcome
That distinction between reasoning and action becomes even scarier when it crosses multi-cloud and hybrid cloud boundaries. Each environment has its own native controls, such as AWS, Microsoft Azure, Google Cloud, SaaS applications, private clouds and on-premises platforms. An action may still begin in AWS, move through Snowflake and SAP and finish in an on-premises database. A control plane limited to one environment isn’t well equipped to establish whether the full cross-system process was properly authorized and completed as intended, and the risk is probably too great of getting it wrong.
Orchestration transports the context in between the handoffs: why the action ran, whether dependencies and approvals were satisfied and, most importantly, whether the process achieved its intended outcome. You get one governed workflow instead of having to reconstruct the path from disconnected system events.
Probabilistic reasoning needs deterministic rails
As agent development spreads across the enterprise, we have to build zero-trust safety nets into AI execution models in order to scale. An agent may choose different paths as conditions change and can revise its diagnosis as new evidence arrives. Workflows that validate AI decisions, data and results can enforce approval requirements for production rollbacks, check downstream readiness and follow a defined recovery path if execution fails.
Cloud-native controls, model policies and platform guardrails already protect their respective domains. Orchestration connects them at the process level, carrying dependencies, approvals, scoped credentials, SLA context, downstream visibility, recovery paths and the audit record across SaaS applications, cloud providers and data centers. The agent invokes an approved workflow, while event-driven orchestration manages how the action proceeds across the estate.
This approach turns existing workload automation into shared execution infrastructure. Recovery workflows, data pipelines and finance processes can support multiple agents, with improvements applied wherever the workflow is called. Model Context Protocol (MCP) standardizes connections to tools and resources, and Agent2Agent (A2A) supports collaboration between agents. The orchestration layer supplies the operating context and control.
A practical AI readiness test for IT Ops
The value of agent adoption becomes measurable when teams define a pre-agent baseline and compare the same metrics across a consistent scope of work. For IT Ops, those metrics may include automation coverage, manual handoffs, SLA attainment and, for recovery use cases, MTTR. The Tokenomics Foundation’s AI value classification framework also recommends accounting for whether outputs meet an established quality threshold and for any new review, rework or escalation the AI creates. This produces a more defensible view of AI’s impact than gross efficiency gains alone. To deliver that value at scale, organizations must expand agent-driven work without adding more coordination work for IT Ops.
The following questions test that foundation:
Can the agent-initiated action be traced from request to outcome across public cloud, private cloud, SaaS applications, data platforms, enterprise applications and on-premises systems?
Does the agent have the context of every system and the resulting automation goal as it crosses environments?
Does its authority remain scoped as the workflow crosses identity and permission models?
Do dependencies, approvals, service-level requirements and recovery policies remain enforceable regardless of where the agent originates?
Is operational ownership clear, and can the responsible team see the end-to-end process state and intervene while work is in flight?
Can the agent invoke existing automation without creating another integration and governance model?
The strongest starting point is a workflow whose intent, authority and accountability are already established and whose operational outcome is measurable. Your team can then apply what worked to subsequent use cases.
The operating advantage grows as more agents use workflows the enterprise has already invested in and validated, extending automation with controls and context in place.
RunMyJobs by Redwood provides the hybrid cloud orchestration layer for this model, giving agents a governed path into existing workflows across cloud services, SaaS applications, data platforms, enterprise applications and on-premises systems.
A business unit wants to put an AI agent on its fulfillment exception process. They’ve found a process with enough variance to justify AI, enough repetitive manual work to make automation attractive and enough business value to get leadership’s attention.
Now, they want sign-off from the architecture team, and not just for this agent. For any new agentic application.
You know that if you approve it, the next team will point to this decision. Then the next. Before long, one narrowly approved use case becomes the precedent for how agents act across your hybrid estate.
As you look through the proposal, you search for strong external controls on the agents, because you know that whether the agent is smart enough isn’t the issue. In a complex business process, an agent can reason perfectly and still become the riskiest participant in the chain if the architecture can’t prove what it touched, what it could’ve touched and what happened after it acted.
The precedent is bigger than the use case
Most AI governance conversations still start too close to the agent: with the model, the prompt, the runtime, the framework, the evaluation scores.
Those do matter, but they’re not the part you’ll be asked to defend when the agent triggers something downstream.
What you’re really approving is an execution model. Can an AI-powered decision leave the tool, cloud service or application where it originated and act safely across the systems that run the business?
For example, a fulfillment process may cross an ERP system, a warehouse platform, a data pipeline, a service management workflow and an on-premises dependency that’s been stable for years. Each domain has its own controls; each one can prove its own piece. But the business process doesn’t care where the boundaries are.
You already know how these environments accumulate, in waves. These cloud migration waves move important workloads forward, but the execution paths underneath them don’t always modernize at the same pace. A polling job becomes the bridge, a script becomes the handoff and a temporary trigger becomes production infrastructure because the business keeps depending on it.
Take an order-to-cash path as an example: a bank file, an older scheduler, an ERP update, shell scripts, a cloud landing zone, an event rule, a transformation job and a warehouse load. None of those pieces is inherently wrong. The issue is that the process now spans multiple systems, teams and control planes.
When someone asks you to “agentify” that kind of process, you can’t avoid the architectural question: what can the agent decide, and what can your estate prove it’s safe to do?
Gartner predicts that more than 40% of agentic AI projects will be scrapped by the end of 2027. The surviving projects will not only have better agents, but also a governed path to production.
Proof of execution
Most teams aren’t training foundation models from scratch. They’re assembling agents from managed models, cloud AI services, copilots, agent frameworks, internal APIs and existing workflow logic. These agents may be able to reason through decisions, but the architecture still has to answer the questions that determine whether it can act:
Who owns the workflow after the agent triggers it?
Who is watching the process end to end?
What exactly can the agent touch?
Which steps require approval or validation?
What dependencies have to resolve before execution continues?
Can an in-flight action be stopped before it completes?
Can security, legal and compliance prove what happened afterward?
Real trust in agentic AI comes from what the execution path can enforce: scoped identity, executable guardrails, downstream visibility, deterministic controls and an audit trail native to the workflow. The agent can evaluate options freely. What it can do in production shouldn’t expand because its reasoning sounded convincing.
Open protocols such as Model Context Protocol (MCP) and Agent2Agent (A2A) reduce the need to solve connectivity per agent, per vendor and per model update. But connectivity doesn’t settle the architecture question. Without a governed access point into the hybrid estate, each new agent arrives with its own identity decisions, logging assumptions, rollback plan and exception path. Pilot momentum can, therefore, turn into technical debt.
Orchestration carries the action from connection to completion, under the controls the business requires.
Give the agent a governed route
You don’t need a longer AI policy as much as you need a controlled execution path. AI agent actions should route through the same kind of layer that already governs critical workflows across cloud, enterprise applications, data platforms and on-premises systems.
That changes your review:
The agent gets a governed interface, not a direct line to production systems
Workflows exposed through MCP can be scoped to exactly what the agent is allowed to do
The same access model used for human-triggered jobs can apply when an agent initiates the action
If an agent-triggered step needs to stop midstream, it should use the same control path as any other failed job, stuck execution or blocked dependency. Audit should work the same way: a byproduct of execution, not a separate reconstruction from scattered logs.
Before you sign off
So what do you tell the business unit this week?
Approving as-is is hard if the process underneath has no single place tracking what ran, what depended on what or how to stop the action midstream. Sending it back with no path forward only guarantees the same request will come from another team.
The approvable answer is conditional: route the agent’s actions through a governed orchestration layer before it touches the business process.
Then, human-triggered and agent-triggered steps can report through the same layer. The distance between “the agent decided” and “the work safely happened” closes because something sits between reasoning and execution, not because the agent got better at reasoning.
RunMyJobs by Redwood helps you build that governed layer, so you can orchestrate hybrid workflows across cloud, enterprise applications, data platforms and on-premises systems with the visibility, control and auditability agentic AI requires.
I’ve sat in enough SAP Integrated Business Planning (IBP) rollout conversations to notice a pattern: almost everyone talks about the planning model, and almost no one talks about what feeds it. That may be fine, until a forecast comes back looking wrong and nobody knows why.
SAP IBP has earned a strong position with SAP customers for good reason. It brings demand planning, inventory optimization, response and supply planning and sales and operations planning into a cloud platform built for modern supply chain volatility. Customer feedback reflects that momentum. SAP recently highlighted SAP IBP’s top customer choice status across major software review platforms. For many SAP-centric enterprises, SAP IBP is becoming the supply chain planning system where teams make decisions they can’t afford to get wrong.
But SAP IBP doesn’t create reliable plans from the platform alone. It depends on accurate, timely data arriving in the right sequence.
Only as strong as your weakest handoff
A demand planning run is only useful if the master data behind it is current. A replenishment recommendation is only reliable if the latest inventory levels, sales activity and supplier performance data made it into the planning model. And a demand forecasting simulation only helps if the upstream data movement completed before the simulation started.
When a planning result in SAP IBP looks off, the problem may have started somewhere else entirely — in SAP S/4HANA, SAP Cloud Integration for data services, a warehouse system, a supplier feed or a non-SAP application that missed its window. Modern supply chain planning depends less on whether individual systems can execute and more on whether their dependencies stay aligned.
That sounds obvious, but it’s exactly where many supply chain planning processes become fragile. Teams tend to focus on the planning application because that’s where the business outcome appears. But the data movement, dependency handling and monitoring supporting it often receive less attention.
In production planning, every delay matters, and the underlying cause is the same whether the trigger is SAP IBP or the shop-floor data pipelines feeding SAP production planning. A late data load can translate directly into excess inventory, the wrong replenishment signal or a planning cycle that finishes after operations needed to act. For supply chain planners, the cost is a missed window to respond to something that would’ve been fixable an hour earlier.
The gold-standard engine behind SAP IBP forecasts
SAP IBP is designed to support sales and operations planning (S&OP), demand forecasting, inventory optimization, response planning and supply planning in a single cloud-based environment. It helps supply chain planners sense demand variability, run scenario planning and align operational plans with financial planning expectations. SAP IBP uses machine learning and predictive analytics to power this, running what-if simulations and flagging disruptions before they compound. To do any of that well, SAP IBP needs high-quality time-series and master data from across the enterprise.
SAP Cloud Integration for data services (SAP CI-DS) is the required engine for that data movement. It connects on-premises systems, cloud applications and SAP IBP across a hybrid IT landscape, so planning processes work from current data rather than yesterday’s snapshot. In many cases, SAP CI-DS is the operational bridge between where supply chain data lives and where planning decisions are made.
When SAP CI-DS tasks run cleanly, the process looks uneventful. Data arrives, planning templates execute, reports refresh and business users get what they expect.
When something goes wrong, the symptoms usually surface later and somewhere else, as a forecast that looks inconsistent because a data load only partially completed or a planning simulation that starts before the required master data is available. The individual task failure often isn’t the whole story.
This isn’t unique to SAP IBP. Recent Redwood Software research found that 8 in 10 manufacturers have automated less than half of their critical data transfers, and more than a quarter still move sensitive documents by hand. Whatever the planning system, the pattern holds: missed or incomplete data movement affects inventory management, procurement, distribution planning and production schedules downstream. If the plan overstates demand, then safety stock, carrying costs and holding costs rise. If it understates demand, stockouts, lead times and customer satisfaction become the problem. Either way, supply chain performance suffers because the system acted on incomplete or late data.
Success in each system ≠ success across the chain
SAP IBP and SAP CI-DS both execute their own work well within their own boundaries. For isolated tasks, native scheduling may be enough. The limit shows up when those tasks become links in a larger supply chain planning process:
SAP S/4HANA updates inventory and order data → SAP CI-DS moves time-series and master data into SAP IBP → SAP IBP runs a planning template → Replenishment reporting refreshes → Operations teams review exceptions
A green status in each tool doesn’t necessarily add up to a trustworthy plan. If one step runs late, partially completes or advances before the required data is ready, the result can still look successful while reflecting the wrong business state. That’s a hard failure mode to catch.
Orchestration is what turns a set of completed tasks into a reliable process. Instead of trusting the clock or a local success message, a modern orchestration platform waits for proof that the process is ready to move forward.
How RunMyJobs supports SAP supply chain planning
SAP IBP and SAP CI-DS are immensely powerful on their own. RunMyJobs by Redwood extracts their full potential by connecting them to the wider enterprise workflows they support. With out-of-the-box connectors for both, you can coordinate planning templates, data movement tasks, monitoring, retries and downstream processes from a central control plane. RunMyJobs’ role as a control plane isn’t limited to SAP; it extends the same coordination to cloud applications, legacy tools and everything else in your landscape, giving your team one place to watch the whole chain instead of piecing it together across systems.
That visibility works best when it’s continuous rather than periodic. RunMyJobs monitors execution in real time and flags SLA risk before a deadline is missed, so a delayed data load or a bottleneck surfaces while there’s still time to act on it, not after a planning cycle has already run on incomplete data.
For SAP IBP, RunMyJobs can retrieve available job scheduling templates, import templates as single jobs or step-by-step chains and submit SAP IBP jobs as part of larger workflows
For SAP CI-DS, RunMyJobs can import existing tasks, execute them, track status through completion or termination and retrieve execution status and logs for centralized monitoring
The planning chain moves because the previous step finished, not because the schedule assumes it should have. That’s especially useful when supply chain planning has to respond to real-time data during demand spikes, supplier delays, inventory exceptions and production capacity constraints. RunMyJobs can trigger the right planning workflow when the business event occurs, stop the process if a dependency fails and alert teams before a late-running cycle affects replenishment or production schedules.
Inside Energizer’s SAP IBP production planning process
Energizer’s planning process is a practical example of this approach working at scale.
Darrin Ward, Business Systems Analyst at Energizer Holdings, explained in a webinar how Energizer optimized and orchestrated its SAP IBP production planning process with RunMyJobs. The team automated many manual steps required to support on-time delivery and coordinated execution across SAP IBP, SAP S/4HANA, SAP CI-DS and Azure Synapse/Data Factory.
RunMyJobs coordinated complex calendaring, proactive alerting and an SAP ECC-to-S/4HANA transition without breaking on-time delivery. That’s the practical test for any orchestration layer: not whether it works when everything is stable, but whether it holds up while the underlying systems are mid-migration.
Treat the pipeline as part of the plan
SAP IBP gives supply chain teams a strong foundation for modern planning. SAP CI-DS provides the required data movement into SAP IBP. Together, they’re central to many SAP supply chain architectures. But the process around them still needs orchestration.
If SAP CI-DS data loads, SAP IBP planning templates, ERP jobs, analytics refreshes and downstream exception workflows are scheduled separately, the planning chain depends on assumptions. If they’re orchestrated together, each step runs based on verified completion and business context.
That’s the difference between a supply chain planning process that usually works and one you can depend on when volatility increases.
I’ve spent nearly three decades working with Redwood Software customers on the jobs, schedulers, scripts and workflows that run large enterprises. What used to be scheduler environments are now hybrid automation estates spanning cloud services, enterprise applications, data platforms and on-premises systems. No two look the same, but the pattern is familiar.
If you already trust RunMyJobs by Redwood with your mission-critical work, you have a foundation many teams are still trying to build. Maybe RunMyJobs runs your SAP processes. Maybe it coordinates your finance workflows, overnight dependencies or reporting chains. Whatever the mix, your most important work already runs through a reliable, governed orchestration layer. The opportunity before you now is to extend that model to the workflows still operating outside it.
In many estates I see, AWS workloads arrive through a different path. For example, a Lambda function solves a specific problem. An AWS Glue job becomes part of a data pipeline. An Amazon S3 bucket turns into a handoff point. A Step Functions workflow grows from a team-level solution into part of a larger business process. Nobody plans these parallel automation models on a whiteboard. They accumulate as practical answers to real needs.
Those AWS services belong in your estate, but the question is whether they should still be operating outside the orchestration model you already trust.
The edges of your coverage
When I talk with customers about AWS, I usually start with a simple exercise: draw the edge of your current RunMyJobs coverage. Not the whole architecture, nor every service inventory — and not the ideal future state. Just the practical boundary between the workflows RunMyJobs already governs and the ones that still operate elsewhere.
That boundary is revealing.
On one side, you have the processes that already inherit the RunMyJobs operating model: dependency logic, calendars, role-based access, approvals, audit history and service-level visibility. On the other side are the workflows that have grown up around AWS, data platforms or SaaS applications on their own timelines. They’re usually perfectly reasonable workflows, but they’re running on a fixed schedule, polling script, local trigger or point integration. Hence, orchestration sprawl happens unintentionally.
I see this most often around processes that cross boundaries: AWS into SAP, AWS into an on-premises application, AWS into a data platform, etc. Each environment has its own logs and controls, but the business process doesn’t stop to respect those boundaries. Hidden risk lives right there.
The next best candidate for moving to RunMyJobs is the workflow that works most days, until it doesn’t.
What’s running on trust?
Look first for workflows that still depend on:
Fixed schedules that assume upstream work finished on time
Polling scripts that check whether a file, job or message is ready
Manual handoffs between AWS and non-AWS systems
Data pipelines where every technical step can succeed, while the business result is late or stale
Those are examples of the AWS workloads RunMyJobs may not know about yet. Some may look small, but if they connect to a business process, they carry operational weight. If they still rely on informal coordination, they carry costs, too.
A bill nobody can quite explain
The cost conversation often starts in AWS, with an instance running longer than expected, a development environment staying up or a batch host waiting most of the day for a few hours of work. FinOps teams can usually identify those patterns. The harder question is what depends on them. No one wants to stop the instance that might still be holding up month-end close or retire the polling script no one fully owns.
That’s why cost optimization is often blocked by uncertainty, not lack of visibility into the bill. When more AWS and hybrid workflows are managed through RunMyJobs, you can see how work starts, waits, runs and completes across the full process. That turns cost from something your team can explain into something your team can act on.
2 versions of the same workflow
AWS-native services are strong building blocks. Step Functions, EventBridge, Lambda, Glue, Managed Workflows for Apache Airflow (MWAA) and other AWS services help teams build scalable, event-driven processes inside AWS. They should keep doing that work.
AWS, SAP, data platforms and on-premises systems each show their own status
The full process has one governed view
A handoff depends on a script, local trigger or manual check
The handoff becomes part of the orchestrated workflow
“Done” means each tool completed its own step
“Done” means the business process completed
Troubleshooting starts with multiple consoles and teams
Troubleshooting starts with the dependency chain
Governance is recreated per tool or team
Governance follows the workflows end to end
Curious whether a specific AWS service is already covered? See the full list ofAWS connectorsRunMyJobs supports today.
The part AI can’t do for you
I get asked about AI in this context more often now: “We’re already putting AI agents on this, so does it matter that some of it still runs outside RunMyJobs?” My answer goes something like: an agent deciding what should happen is not the same as the work safely getting done.
An agent may recommend restarting a failed step, refreshing a data pipeline, triggering a reforecast or escalating an approval. But that action still has to move through the same governed, auditable business processes you already operate. If a workflow sits outside RunMyJobs today, AI doesn’t make it safer by touching it. The handoff still needs ownership, access control, dependency context and an audit trail.
So, coverage matters here too. With capabilities like Model Context Protocol (MCP) support, RunMyJobs can expose existing workflows to AI agents through governed access, rather than giving agents raw access to production systems. Your production workflows remain controlled, governed and scoped to the same permissions and process logic you already trust.
Somewhere in your IT estate tonight, a workload will run that is older than some of the engineers maintaining it. It may close the books, move inventory, trigger replenishment, process settlements or feed a dashboard before the business day starts. It’s survived multiple technology waves because it works. It does what the business needs it to do.
Somewhere else, maybe in the same chain, an AWS Lambda function will fire, or an Azure Data Factory job will transform data. A container task will run. A data platform will load the result into a report that someone depends on tomorrow morning.
Nothing about that combination is unusual anymore. The systems that have carried your business for years now run alongside cloud services built for a different era of speed and scale. Neither is inherently fragile, but the connections between them often become costly points of failure as integration and workflow complexity grow.
No one gets to modernize in a vacuum
Your modernization program is already changing the shape of the business. Applications and workloads are moving to the cloud. SaaS platforms are expanding across functions. Data pipelines are being rebuilt for speed, scale and AI readiness. But modernization doesn’t arrive as a clean cutover. You prioritize the areas with the clearest business value first, while the systems that already run the business keep running.
That is what makes hybrid cloud environments difficult. You’re not replacing one world with another. You’re running decades of technology at the same time across cloud services, enterprise applications, data platforms, on-premises infrastructure and private cloud environments. Every new wave has to connect to what came before it.
Ask anyone who has run a postmortem on a cross-environment failure, and they’ll recognize the typical way this shows up: a legacy batch process completed, an AWS service did what it was supposed to do and both teams have logs that prove their side behaved correctly. Yet, the business process still broke. All the evidence stops at the edge of each system.
That also means the failure lives in a place that doesn’t cleanly belong to anyone. The script holding together the on-prem side and the cloud side may have been written three years ago and never put under version control. It’s both load-bearing and invisible.
Over time, taking the shortest path available on any given day allows your hybrid estate to grow both systems and handoffs simultaneously. You already know what this costs because you’ve probably lived the 2 AM version, when someone is trying to remember who knows what a particular script was supposed to do.
“The job ran” and “the business got what it needed” have never been the same claim, but tooling fragmentation forced you to treat them as if they were. Cloud migration may change where the work runs, but it doesn’t automatically change how it’s coordinated.
The economics of old habits
Cloud changed the cost model faster than most operating models could follow.
In the data center, a lot of habits were rational. Fixed schedules gave you predictability, and extra capacity reduced risk. A server left running overnight didn’t create a new hourly charge, and polling every five minutes was cheap enough to ignore. Move those same patterns into a metered cloud environment, and you’re paying for 20 hours of polling rather than the four hours of true work. For readiness rather than action.
That isn’t getting better on its own. Flexera found that wasted cloud spend rose to 29% in 2026, the first increase in five years. That tracks with the arrival of AI workloads, according to the study.
But cloud cost conversations often get stuck. FinOps can point to all the candidates for waste, and the list is rarely a surprise:
Instances that run long after the workload ends
Environments sized for old peak assumptions
File watchers and polling jobs that could be event-driven
Scripts that exist only to bridge one system to another
Batch hosts no one wants to shut down
The hardest part is proving what happens if you change any of them. You can’t safely stop an instance, retire a script or replace a polling loop if you don’t know which business processes depend on it.
In one recent conversation I had with a senior engineer at a large enterprise assembled through several acquisitions, they described it like this: “Jenkins here, Cron there, an Azure Automation instance nobody fully owns, SAP schedulers running in parallel, Step Functions and Airflow layered in as our data pipelines grew. Each tool has its own team, its own visibility and its own blind spot at the edge. Rather than creating a new version of this problem, AI is raising the cost of the one that’s already there.”
Run a simple version of the math against your own environment.
If you have 500 Amazon EC2 instances averaging $400 per month, and even 20% exist mainly to host, wait for or watch batch work, that’s roughly $480,000 per year before storage, transfer, snapshots or operational overhead. Idle time isn’t theoretical when the meter is always running.
This isn’t just theoretical. We see Redwood Software customers cutting these costs every day.
A global CPG company consolidating decades of manual document processing onto a single orchestration layer and cut document-processing costs by 98%
A large, regulated enterprise bridging legacy batch infrastructure with its cloud environment, removing 59% of peak runtime and 25% of average runtime from its estate without missing a single billing window
Both have hybrid environments where the fix was to govern the handoffs between what already existed, not to engage in another migration.
The way out is not simply to squeeze every workload harder. It’s to change how work starts, waits and stops, and that means solving orchestration tooling sprawl instead of compressing individual runtimes.
Not just another migration
The pain usually shows up when you realize you have many places to schedule work, but no single place to understand the full process. Your instinct could be to just migrate again. Move to a new tool, consolidate, rehost, standardize. And those steps could be necessary, but another migration won’t automatically rebuild the connective layer between systems. If your measure of success is whether every job runs the same way somewhere else, you may have improved the platform while preserving the operating model that created the problem.
Better questions are outcome-based:
Which polling loops can you retire?
Which always-on hosts can start and stop around real workload demand?
Which manual handoffs can become governed workflows?
Which scripts can be replaced instead of recreated?
Which failures can now surface before the business notices?
Which business processes can be monitored end to end, not system by system?
A modern orchestration layer doesn’t ask cloud services, enterprise applications, data platforms and on-premises systems to behave as if they were one technology stack. It gives you one place to coordinate the work between them. The older process can stay. The newer cloud service can stay. But the handoff becomes visible, governed and auditable, with role-based access for who can touch it, an immutable trail of what ran and why and an SLA that predicts a chain trending late while there’s still time to act on it.
That matters now for cost and reliability. And it will matter even more as AI continues to move from pilots to everyday use.
Agents decide, but something else has to execute
The line between cloud modernization and AI readiness is getting thinner and thinner. Most enterprises aren’t building models from scratch. They’re layering agents onto cloud services, managed models and AI-enabled applications and asking those agents to do more than answer questions. Increasingly, they need to trigger workflows, remediate failures and escalate approvals.
But an agent that decides isn’t the same thing as work that gets done. A recommendation to release an order, correct a billing run or kick off a fulfillment path still has to travel through the same deterministic, auditable execution layer as everything else in your hybrid estate.
That’s the part almost nobody has built well, and it’s the same problem as the cost story above, not a separate one. If a handoff is invisible to IT Ops today, it doesn’t become safe or governed just because an AI agent is the one initiating it. The value doesn’t come from the AI alone, but from the blend of judgment and execution and the space between them is where the real work is.
Make decades of tech governable
As you know, forcing every new service into one architectural pattern simply won’t work. The systems running your business have earned their place, and the newer services you’re adopting are there for good reasons: speed, scale, elasticity, AI readiness. You can’t operate in such complexity on trust alone.
Cost is often the first place this becomes visible. Handoffs that were once absorbed as operational noise now show up as workloads you can’t safely optimize, instances you can’t confidently stop, scripts you can’t retire and business processes whose true cost you can’t explain. The more your hybrid estate grows, the more expensive those unknowns become.
More running in the cloud doesn’t mean more modern. What truly supports modernization in the long run is having a modern application and data workflow orchestration platform. It must deliver a governed operating model for each new service, pipeline or AI-enabled workflow to inherit — the same role-based access, audit trail and SLA visibility, applied consistently instead of rebuilt per tool.
Redwood brings old and new together under one orchestration layer. See how you could bemanaging hybrid cloud workflowsacross cloud services, enterprise applications, data platforms and on-prem systems with end-to-end visibility and control.